
AI Video Assistant
Services:
- Product design
- Full-stack development
- AI engineering (RAG)
- Video processing pipeline
- Multi-tenant SaaS architecture
Industry:
- Healthcare education · Professional training · SaaS
Technology:
- Angular 21
- NestJS / TypeORM
- PostgreSQL 16 + pgvector
- OpenAI GPT & embeddings
- Google Gemini
- PyannoteAI diarization
- Vimeo API, ffmpeg
- Tailwind CSS, Bun, Supabase
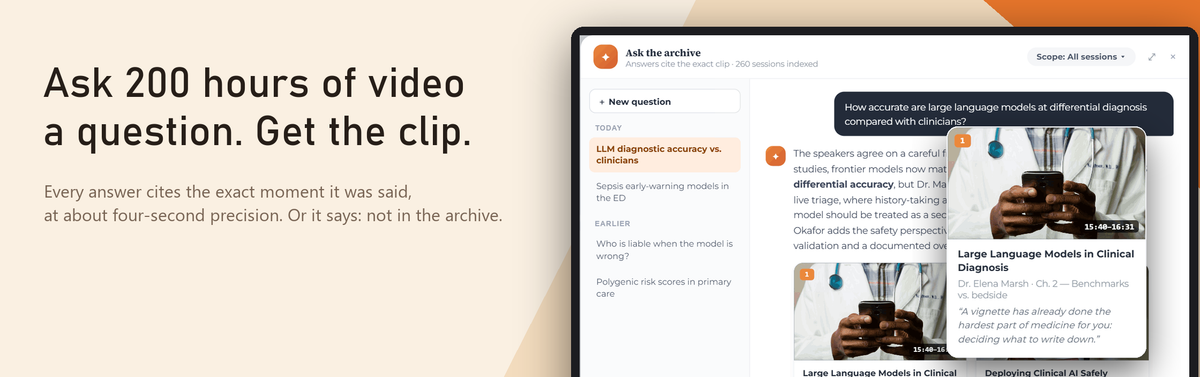
Someone asks you how accurate language models are at differential diagnosis. You know a speaker covered it. Was it the spring summit or the radiology panel? Forty minutes in, or ten? You used to open the recording and scrub. Now you type the question and get a two-paragraph answer and two clips, cued to 15:40 and 21:08, where the speakers actually said it. If nobody said it, the archive tells you so instead of making it up.
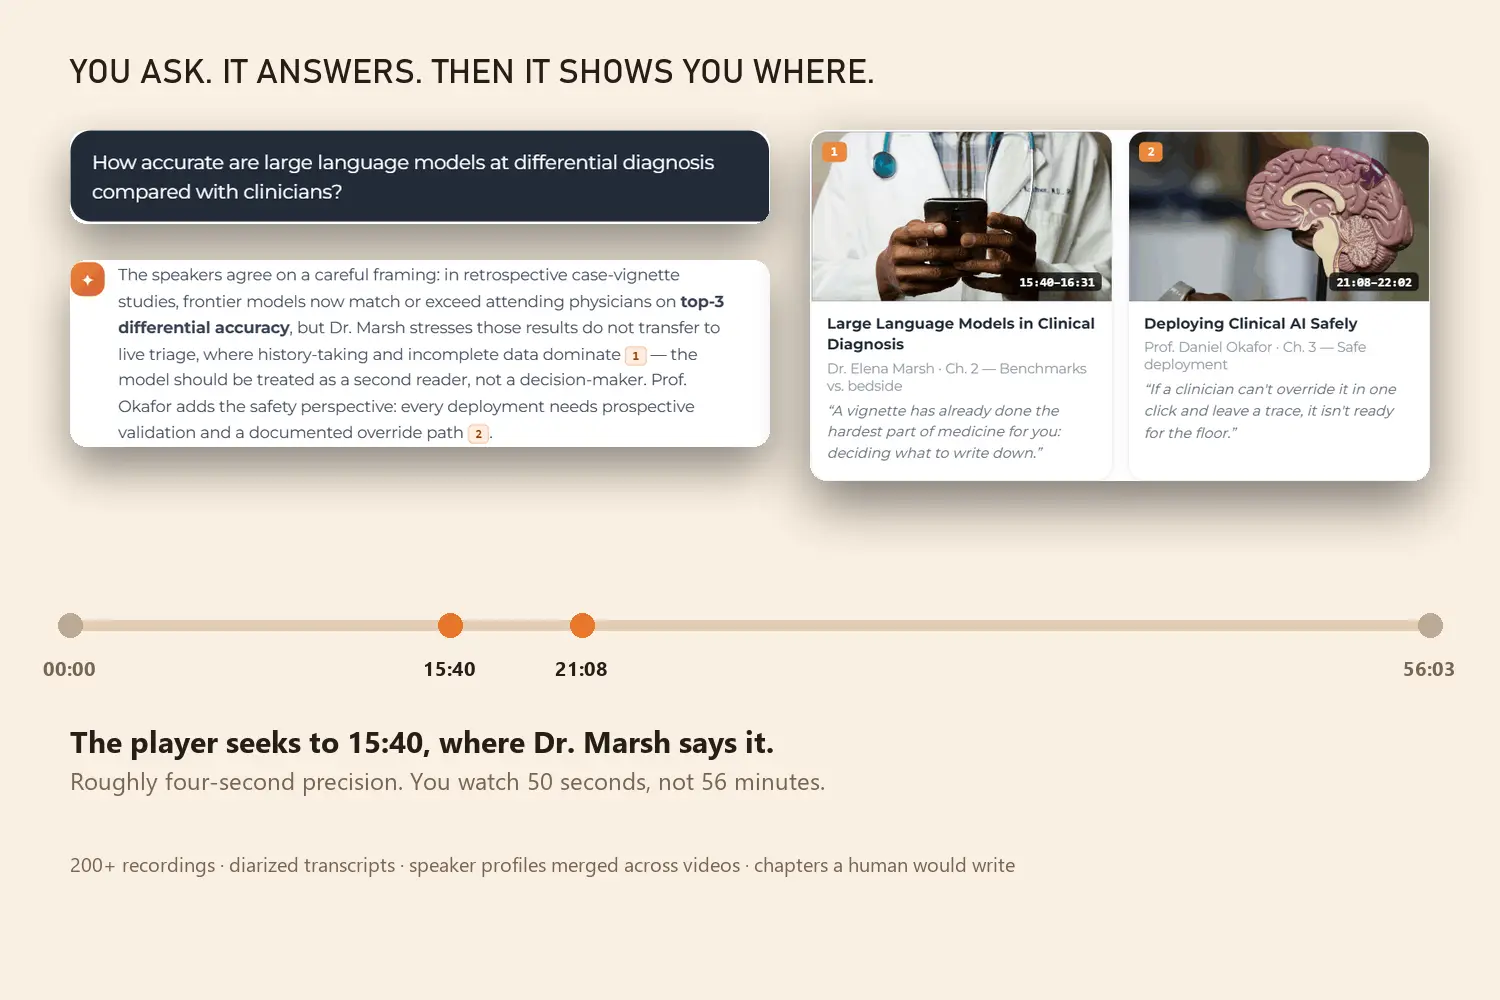
You ask. It answers. Then it shows you where. Every recording arrives with a transcript that knows who is speaking, a speaker profile that merges the same person across dozens of videos, and a chapter list that tells you in ten seconds whether an hour-long session deserves your time. Ask a question and the answer comes with numbered citations; click one and the player seeks to the moment the point was made, at roughly four-second precision. Type @ to ask one speaker, @@ to ask one session, or ask how a speaker’s view on a topic evolved across years of talks.
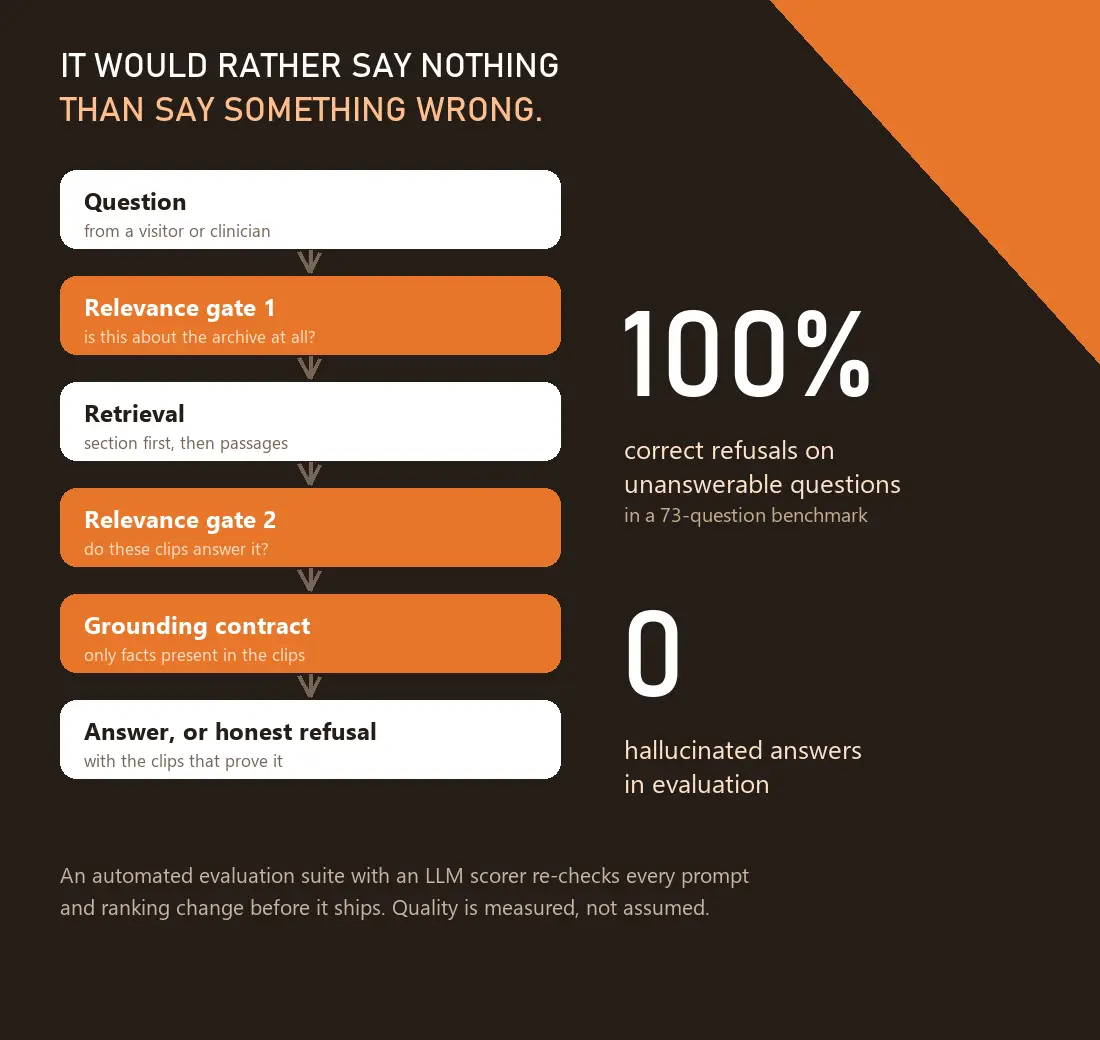
It would rather say nothing than say something wrong. In a regulated field a confident wrong answer is worse than none, so the system is built to refuse. Two relevance gates stop off-topic questions before any model is called. Retrieval runs section-first, then passage by passage, so the answer comes from the right part of the right lecture. A strict grounding contract allows only facts present in the retrieved clips. On the 73-question benchmark the system declined every unanswerable question instead of guessing, and an automated evaluation suite with an LLM scorer re-checks every prompt and ranking change before it ships.
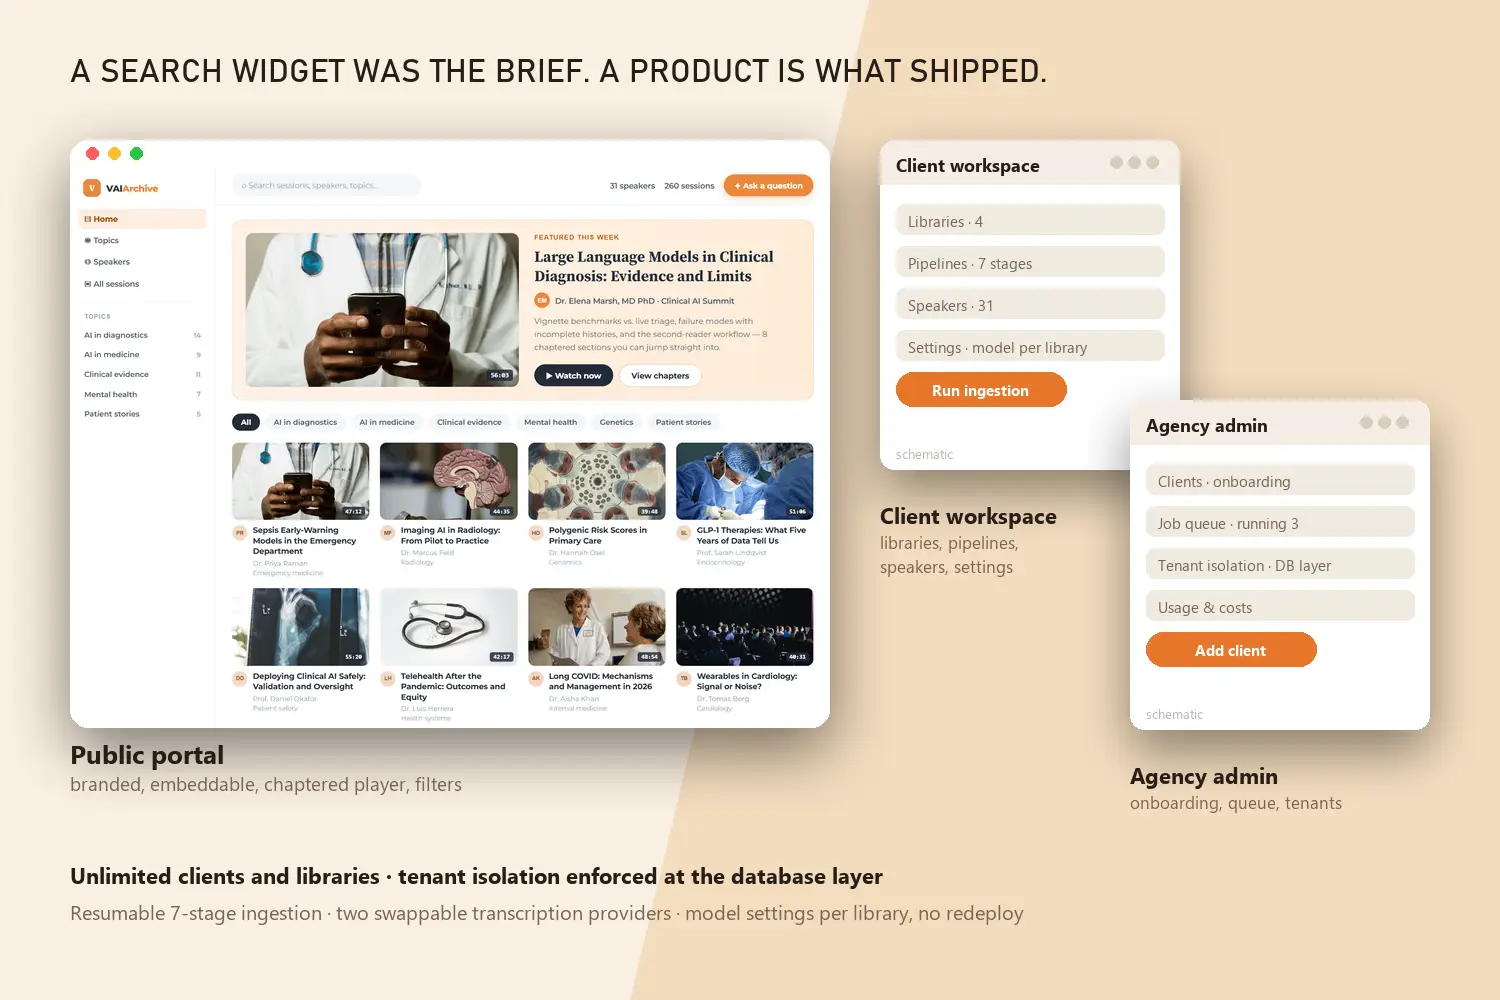
A search widget was the brief. A product is what shipped. A branded public portal with embedded player, chapter navigation, filters, custom CSS and a domain allow-list for embedding. A client workspace for libraries, pipelines, speakers and settings. An agency-side admin for onboarding clients and watching the job queue. Underneath, a resumable seven-stage ingestion pipeline with two swappable transcription providers and per-library model settings, so quality is tuned without a redeploy. Unlimited clients and libraries, tenant isolation enforced at the database layer: a passive archive became an asset the organization can brand, embed and extend to new audiences.
If this sounds like your organization: you record everything and nobody watches it back. We make it answer questions, with receipts.
Let's get started!

Awesome!
We’ll be right back for a good talk.
Cheers ?
